

Welcome back to Altered Craft’s weekly AI review for developers. Thank you for reading, and for the replies and shares that keep this going. The thread this week is how much model a job really needs. Meta’s orchestrator does no reasoning, Cloudflare extracts without an LLM, Mistral forecasts on a CPU, and a 298-question test asks whether an agent loop earns its place. Anthropic’s own numbers suggest the judgment about where to spend intelligence is becoming the developer’s main job.
TUTORIALS & CASE STUDIES
We open with an Anthropic case study of it’s own numbers on where human effort goes once agents do most of the work. Two pieces on building the system around the agent follow, and two tests of whether a loop or a score earns your trust close the section.
Inside Anthropic: Agent Hours Outnumber Humans Six to One
Estimated read time: 14 min
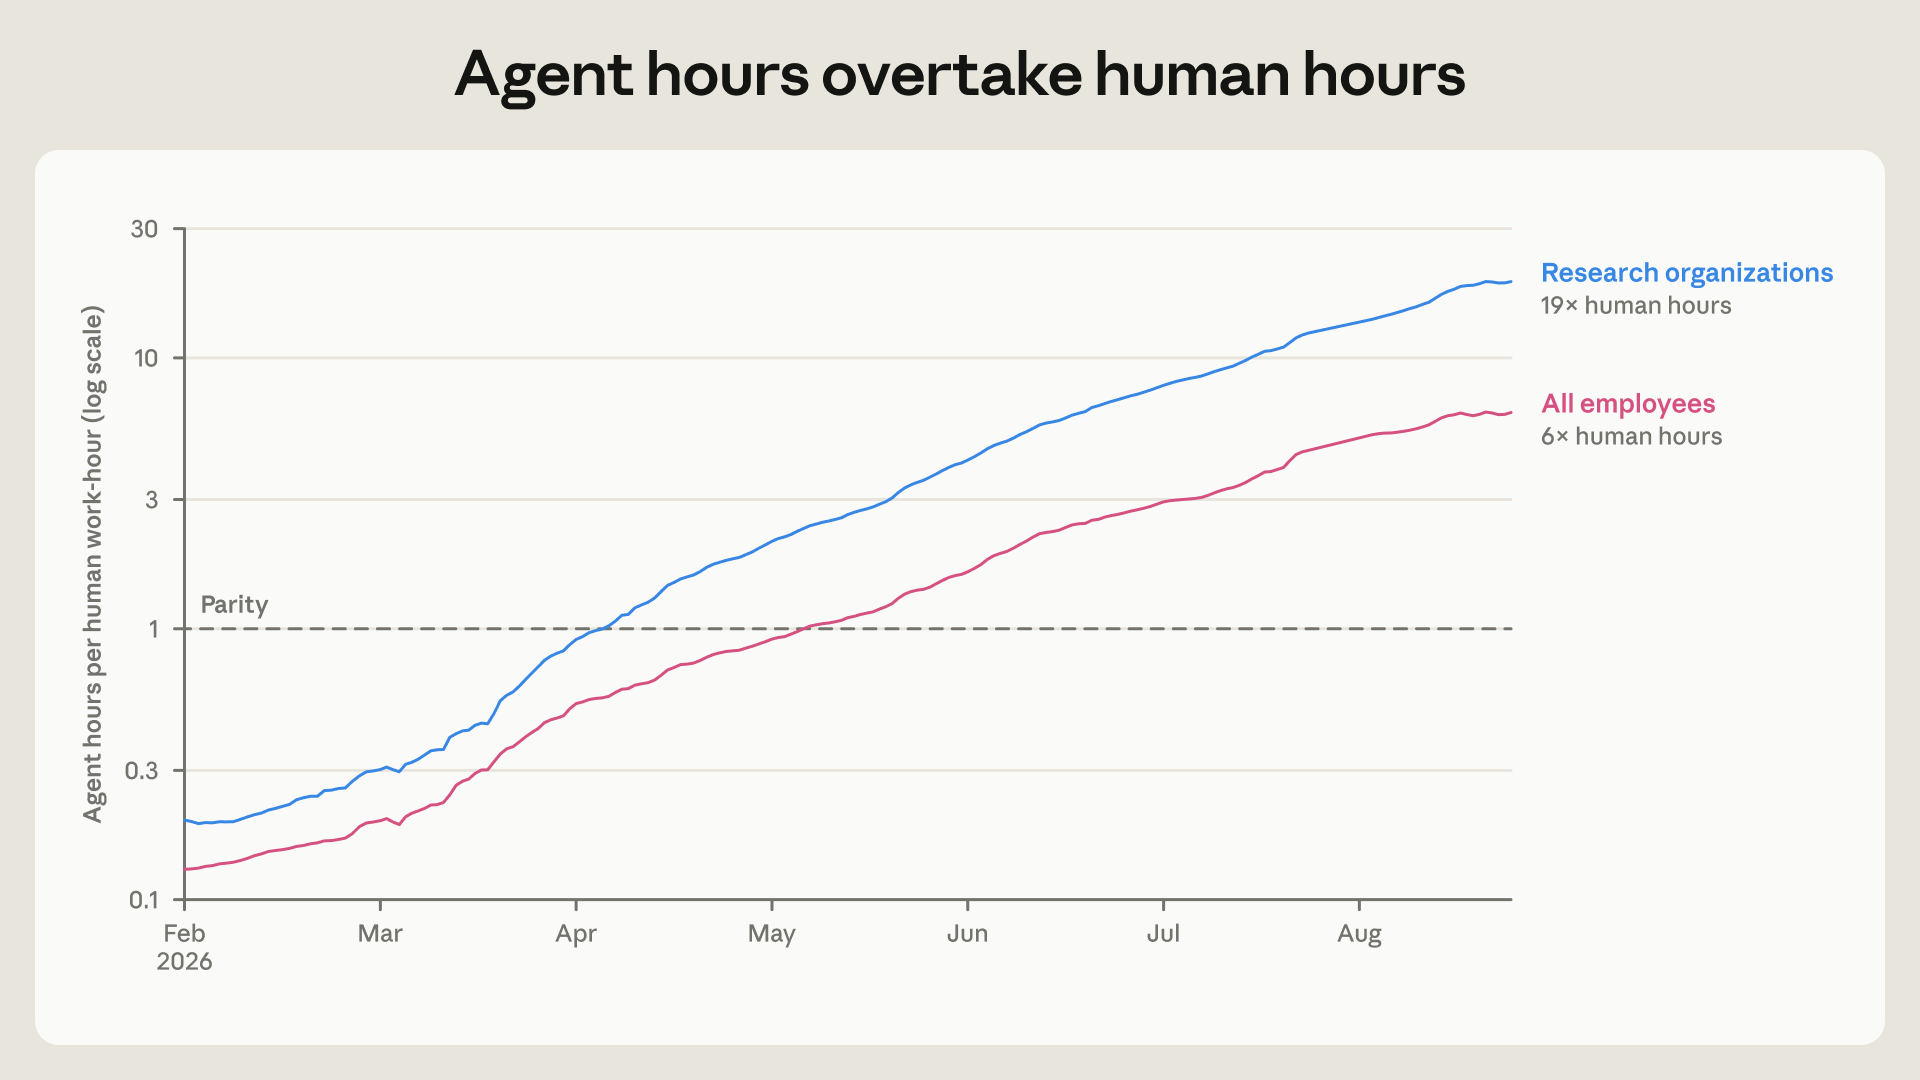
Following our look at Anthropic’s agent-era source control[1] last week, the company’s internal employment data shows junior technical hiring falling from 27% to 9% of hires while agent hours outnumber employee hours six to one, with output per person climbing across engineering, sales, and legal work.
Why this matters: As agents absorb implementation work, the scarce skill becomes judgment about what to run and how to review it. That is the skill worth building now, whatever your domain.
[1] Anthropic Replaced Git With Scion
The Thin Orchestrator: Why Meta’s Agent Router Does No Work
Estimated read time: 9 min
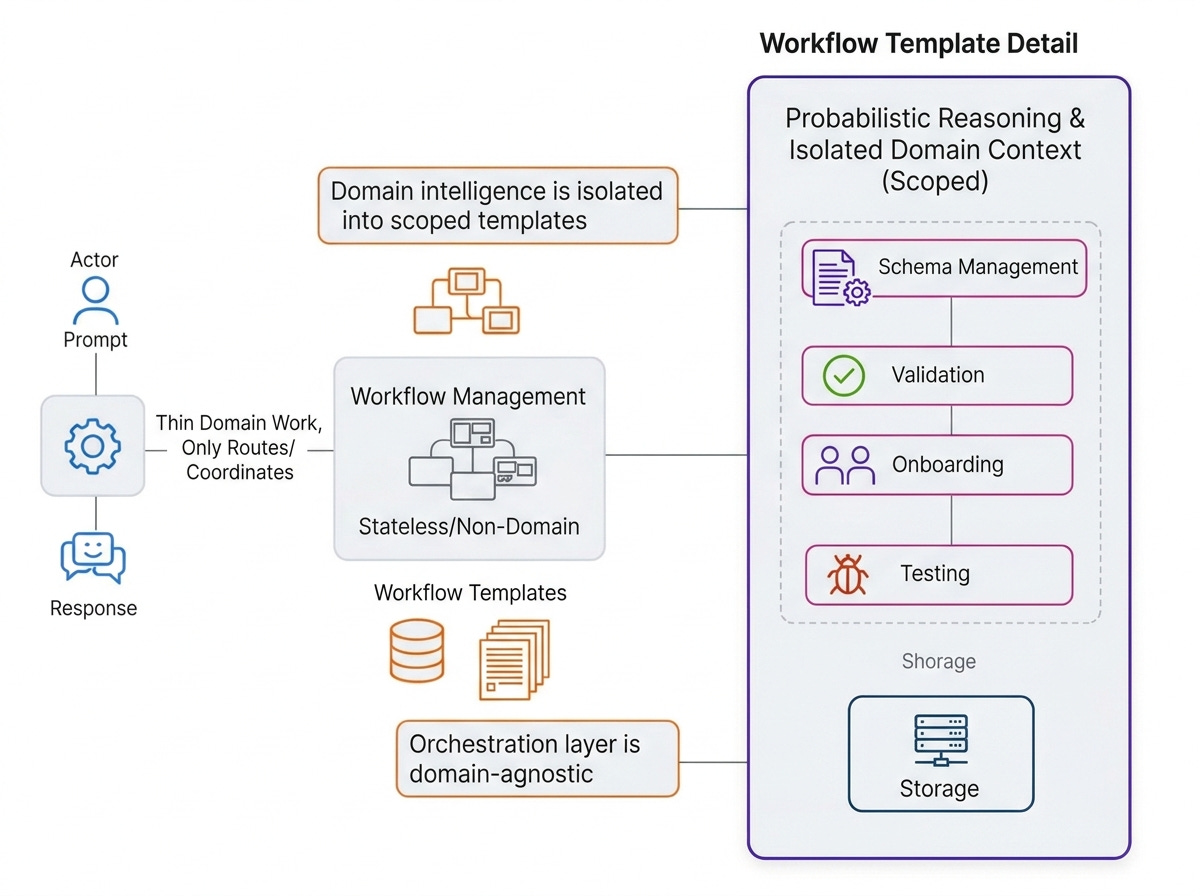
One answer to what to run: Meta’s data pipeline agents went from days of work to under an hour by making the orchestrator dumber. A 1,300-line router that does zero domain reasoning sequences 14 specialized subagents, each with isolated context and runtime-loaded knowledge files.
The pattern: If your orchestrator is making domain decisions, it is doing too much. Keep routing deterministic and push reasoning into isolated, domain-scoped subagents that load only the knowledge they need.
Agents CLI Extensions: Running LangChain (and Your Own Deploy Policy) on Google’s Agent Toolchain
Estimated read time: 12 min
Also building around the agent rather than inside it, Google’s Agents CLI now ships an extension system that swaps framework-coupled commands without forking the tool. The walkthrough scaffolds a LangChain agent through the full lifecycle, then wraps deploy with a custom SBOM compliance scan.
What this enables: Extensions distributed as pinned Git repos let you keep a toolchain’s deploy, eval, and observability work while replacing only the commands that assume a specific agent framework.
Does Agentic RAG Actually Retrieve Better Evidence? A 298-Question Test
Estimated read time: 9 min
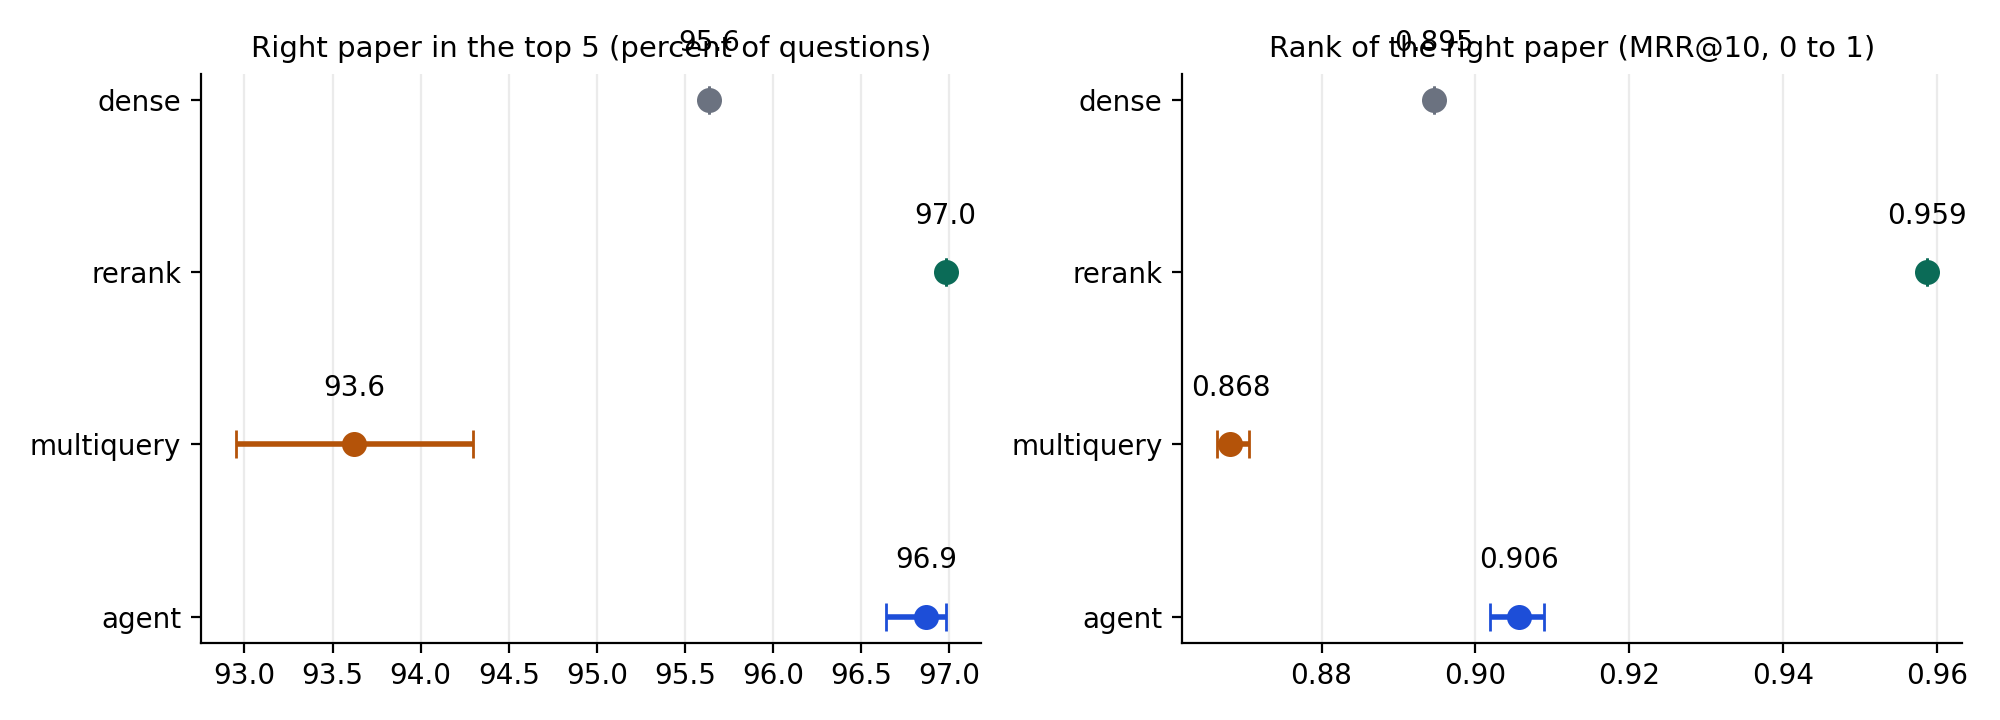
Turning from building to measuring, this benchmark pits agentic RAG against a standard retrieval baseline across 298 questions, asking whether the agent loop actually surfaces better evidence or simply adds latency and cost to the same answers.
Try this: Before adding an agent loop to your RAG pipeline, measure retrieval quality against a plain baseline on your own questions. The extra loop has to earn its latency.
Decision Models for Evals: Tune the Threshold Before You Trust the Score
Estimated read time: 13 min
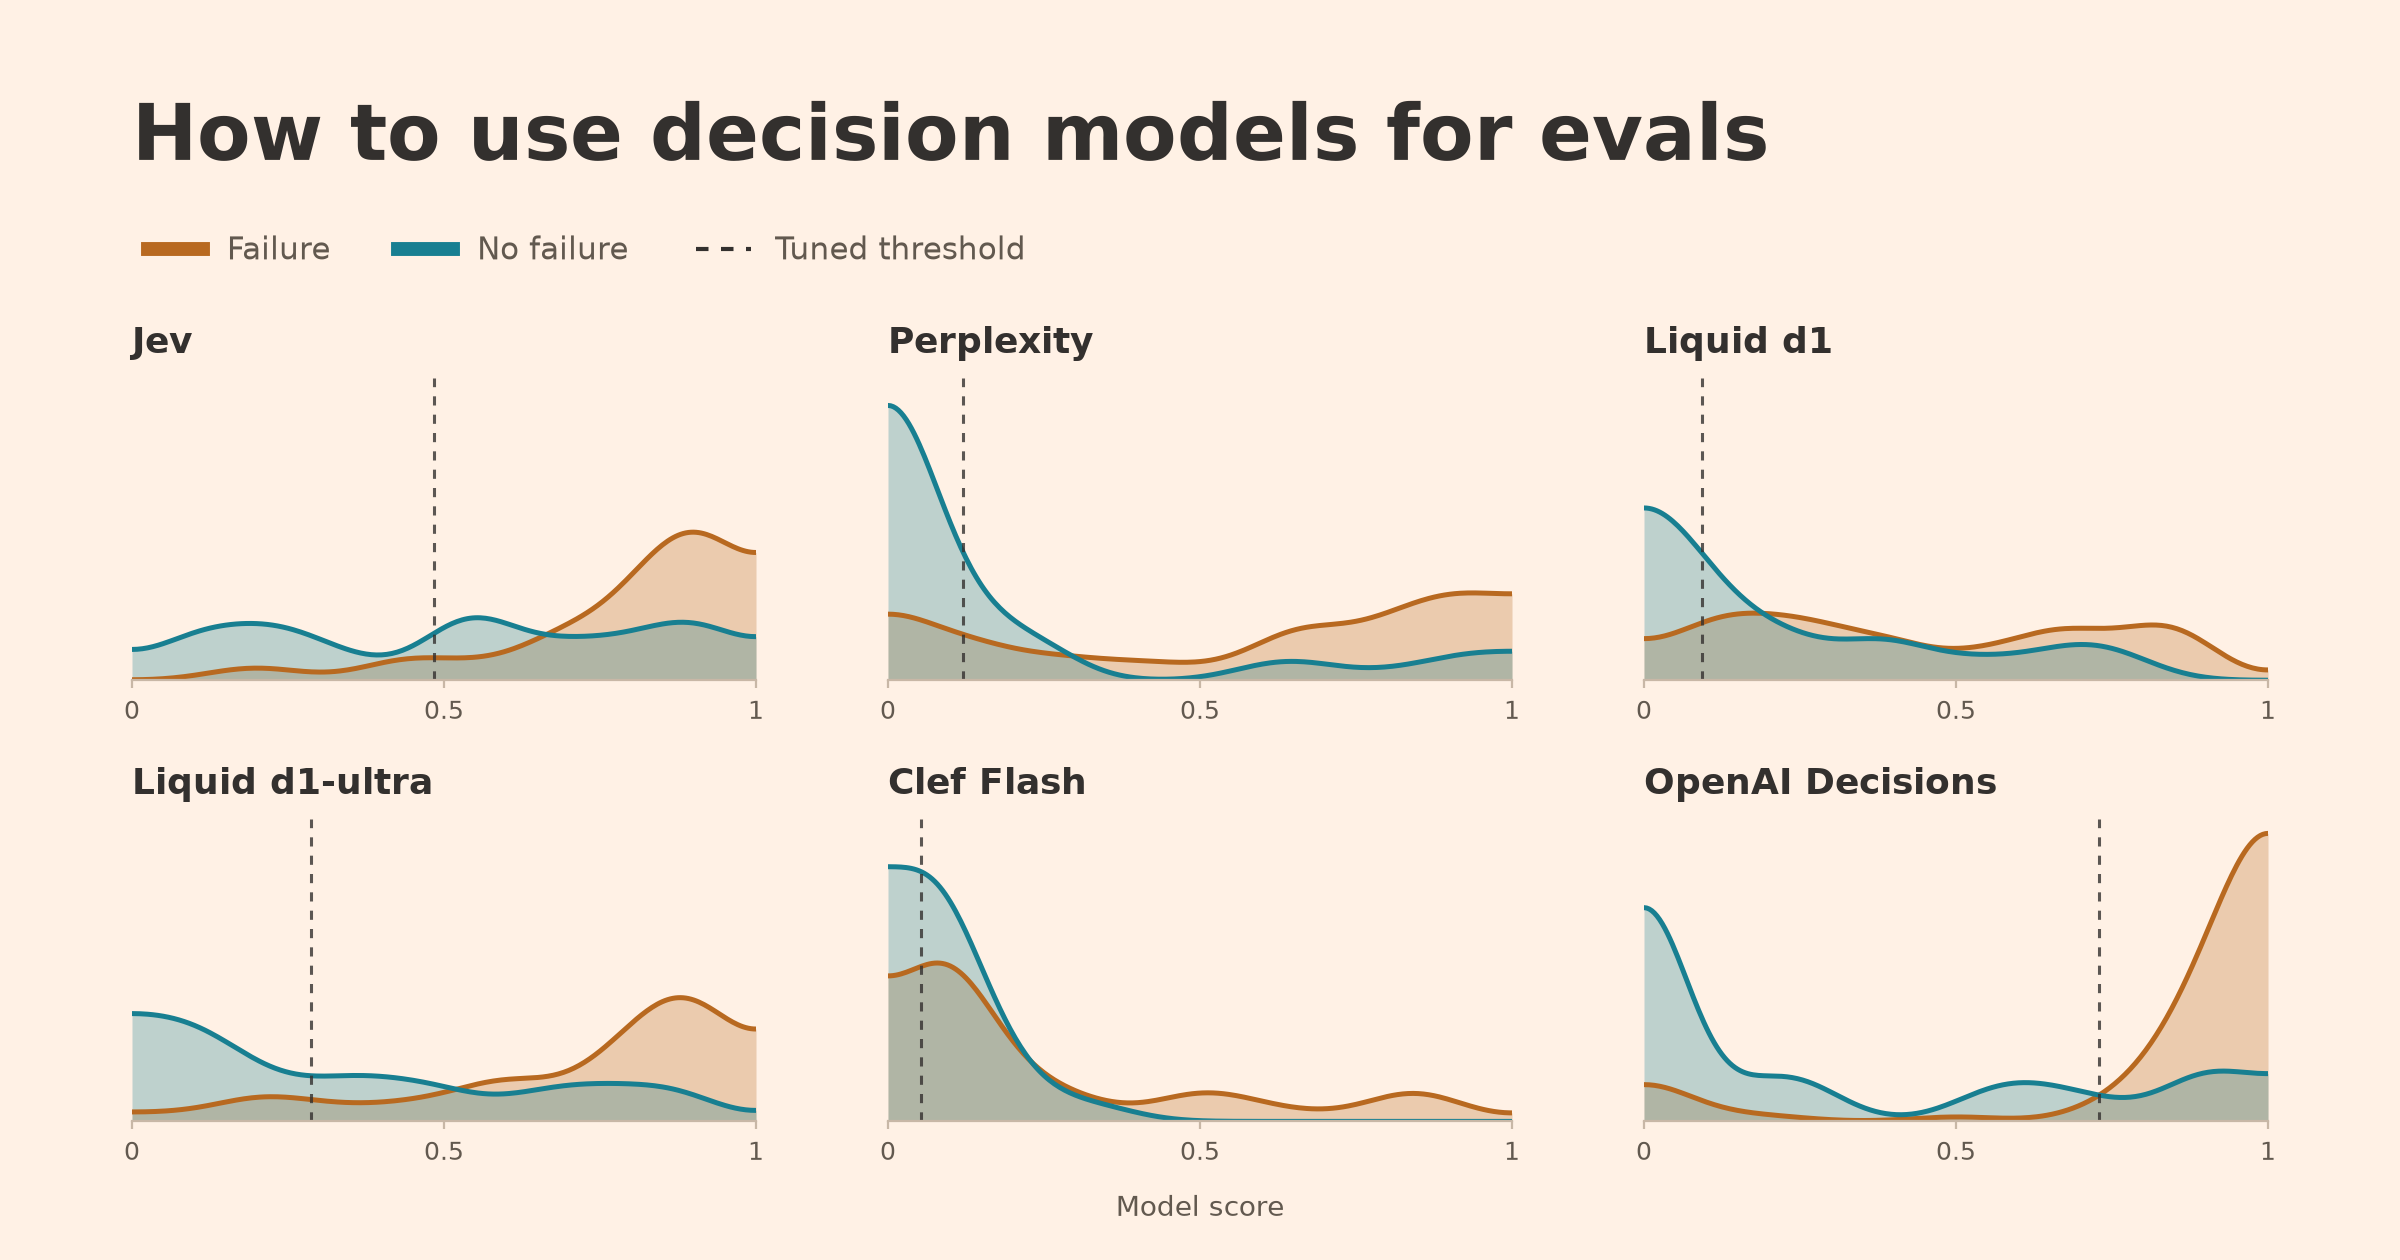
Extending our hands-on week with TypeSafe’s Jev[2] from last week, this walkthrough shows that decision models promise cheap classification for automated evals, but shipping with the default 0.50 threshold leaves performance on the table. It tunes thresholds, sets precision and recall floors, and checks whether scores are calibrated before trusting them.
In practice: Pick your precision and recall minimums first, tune each model’s threshold on labeled traces, and only then compare models on cost. The default threshold is rarely the right one.
[2] A Week Inside Jev: What a Non-Generative Decision Model Is Actually Good For
TOOLS
The tools run from cheaper to cheapest: a fast agentic model, a coding model for your laptop, forecasting on a CPU, extraction with no output tokens at all, flat-rate web access for agents, and a harness that never repeats paid work.
MiniMax M3.1 Flash Targets Agentic Work at $0.15 per Million Tokens
Estimated read time: 3 min
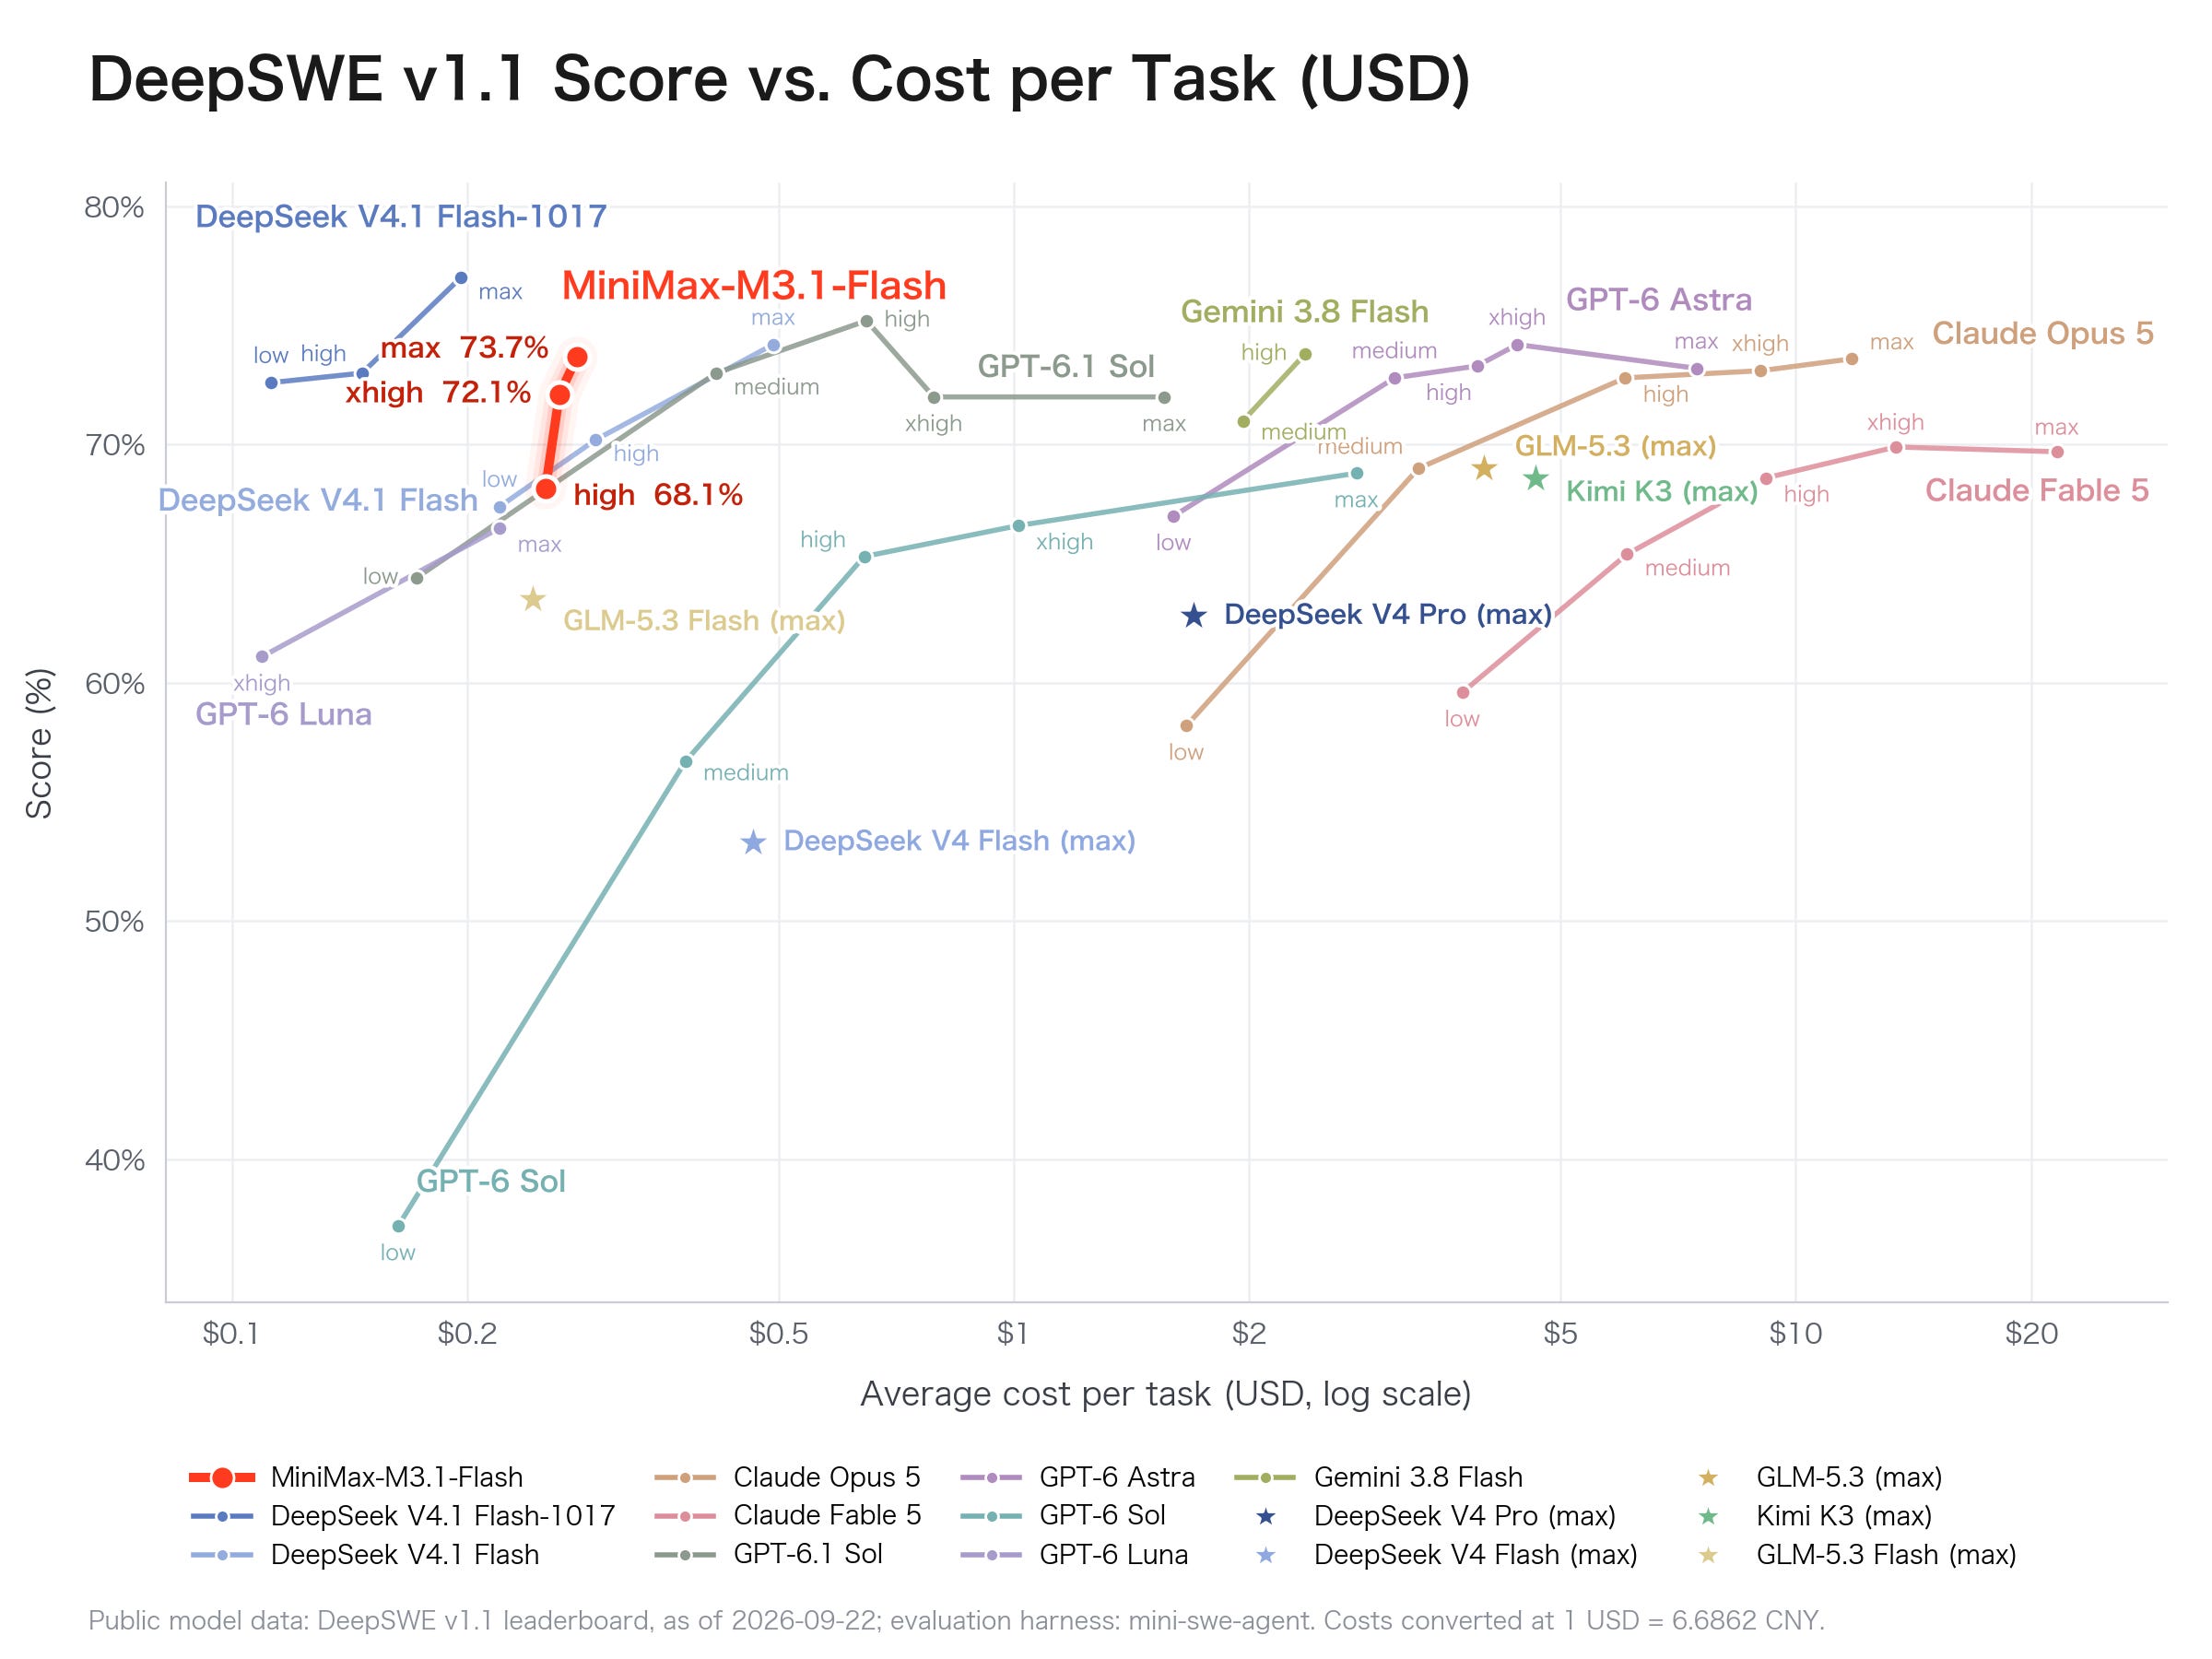
MiniMax releases M3.1 Flash, posting 73.7% on DeepSWE and 61.7 on OSWorld V2 while cutting agentic task cost by 70%. Output runs at more than 200 tokens per second, and MiniMax says open weights will follow.
Why now: Cheap, fast models are closing in on frontier coding and computer-use scores. Long agent loops that were too costly to run routinely are becoming affordable.
Flint: A 40B MoE Coding Model Built to Run on Your Laptop
Estimated read time: 7 min
Moving the savings onto your own hardware, Recursive releases Flint, a 40B mixture-of-experts model activating 2.5B parameters per token and hitting over 125 tokens per second on an M4 Pro MacBook. Apache-2.0 weights, 512k context, and an automated research loop that built it in four months.
The opportunity: Local agentic coding is getting practical. Pull Flint from Hugging Face, run it in Ollama or LM Studio, and keep your code off remote servers.
Timestral: Mistral’s Time-Series Foundation Models Run on CPU
Estimated read time: 8 min
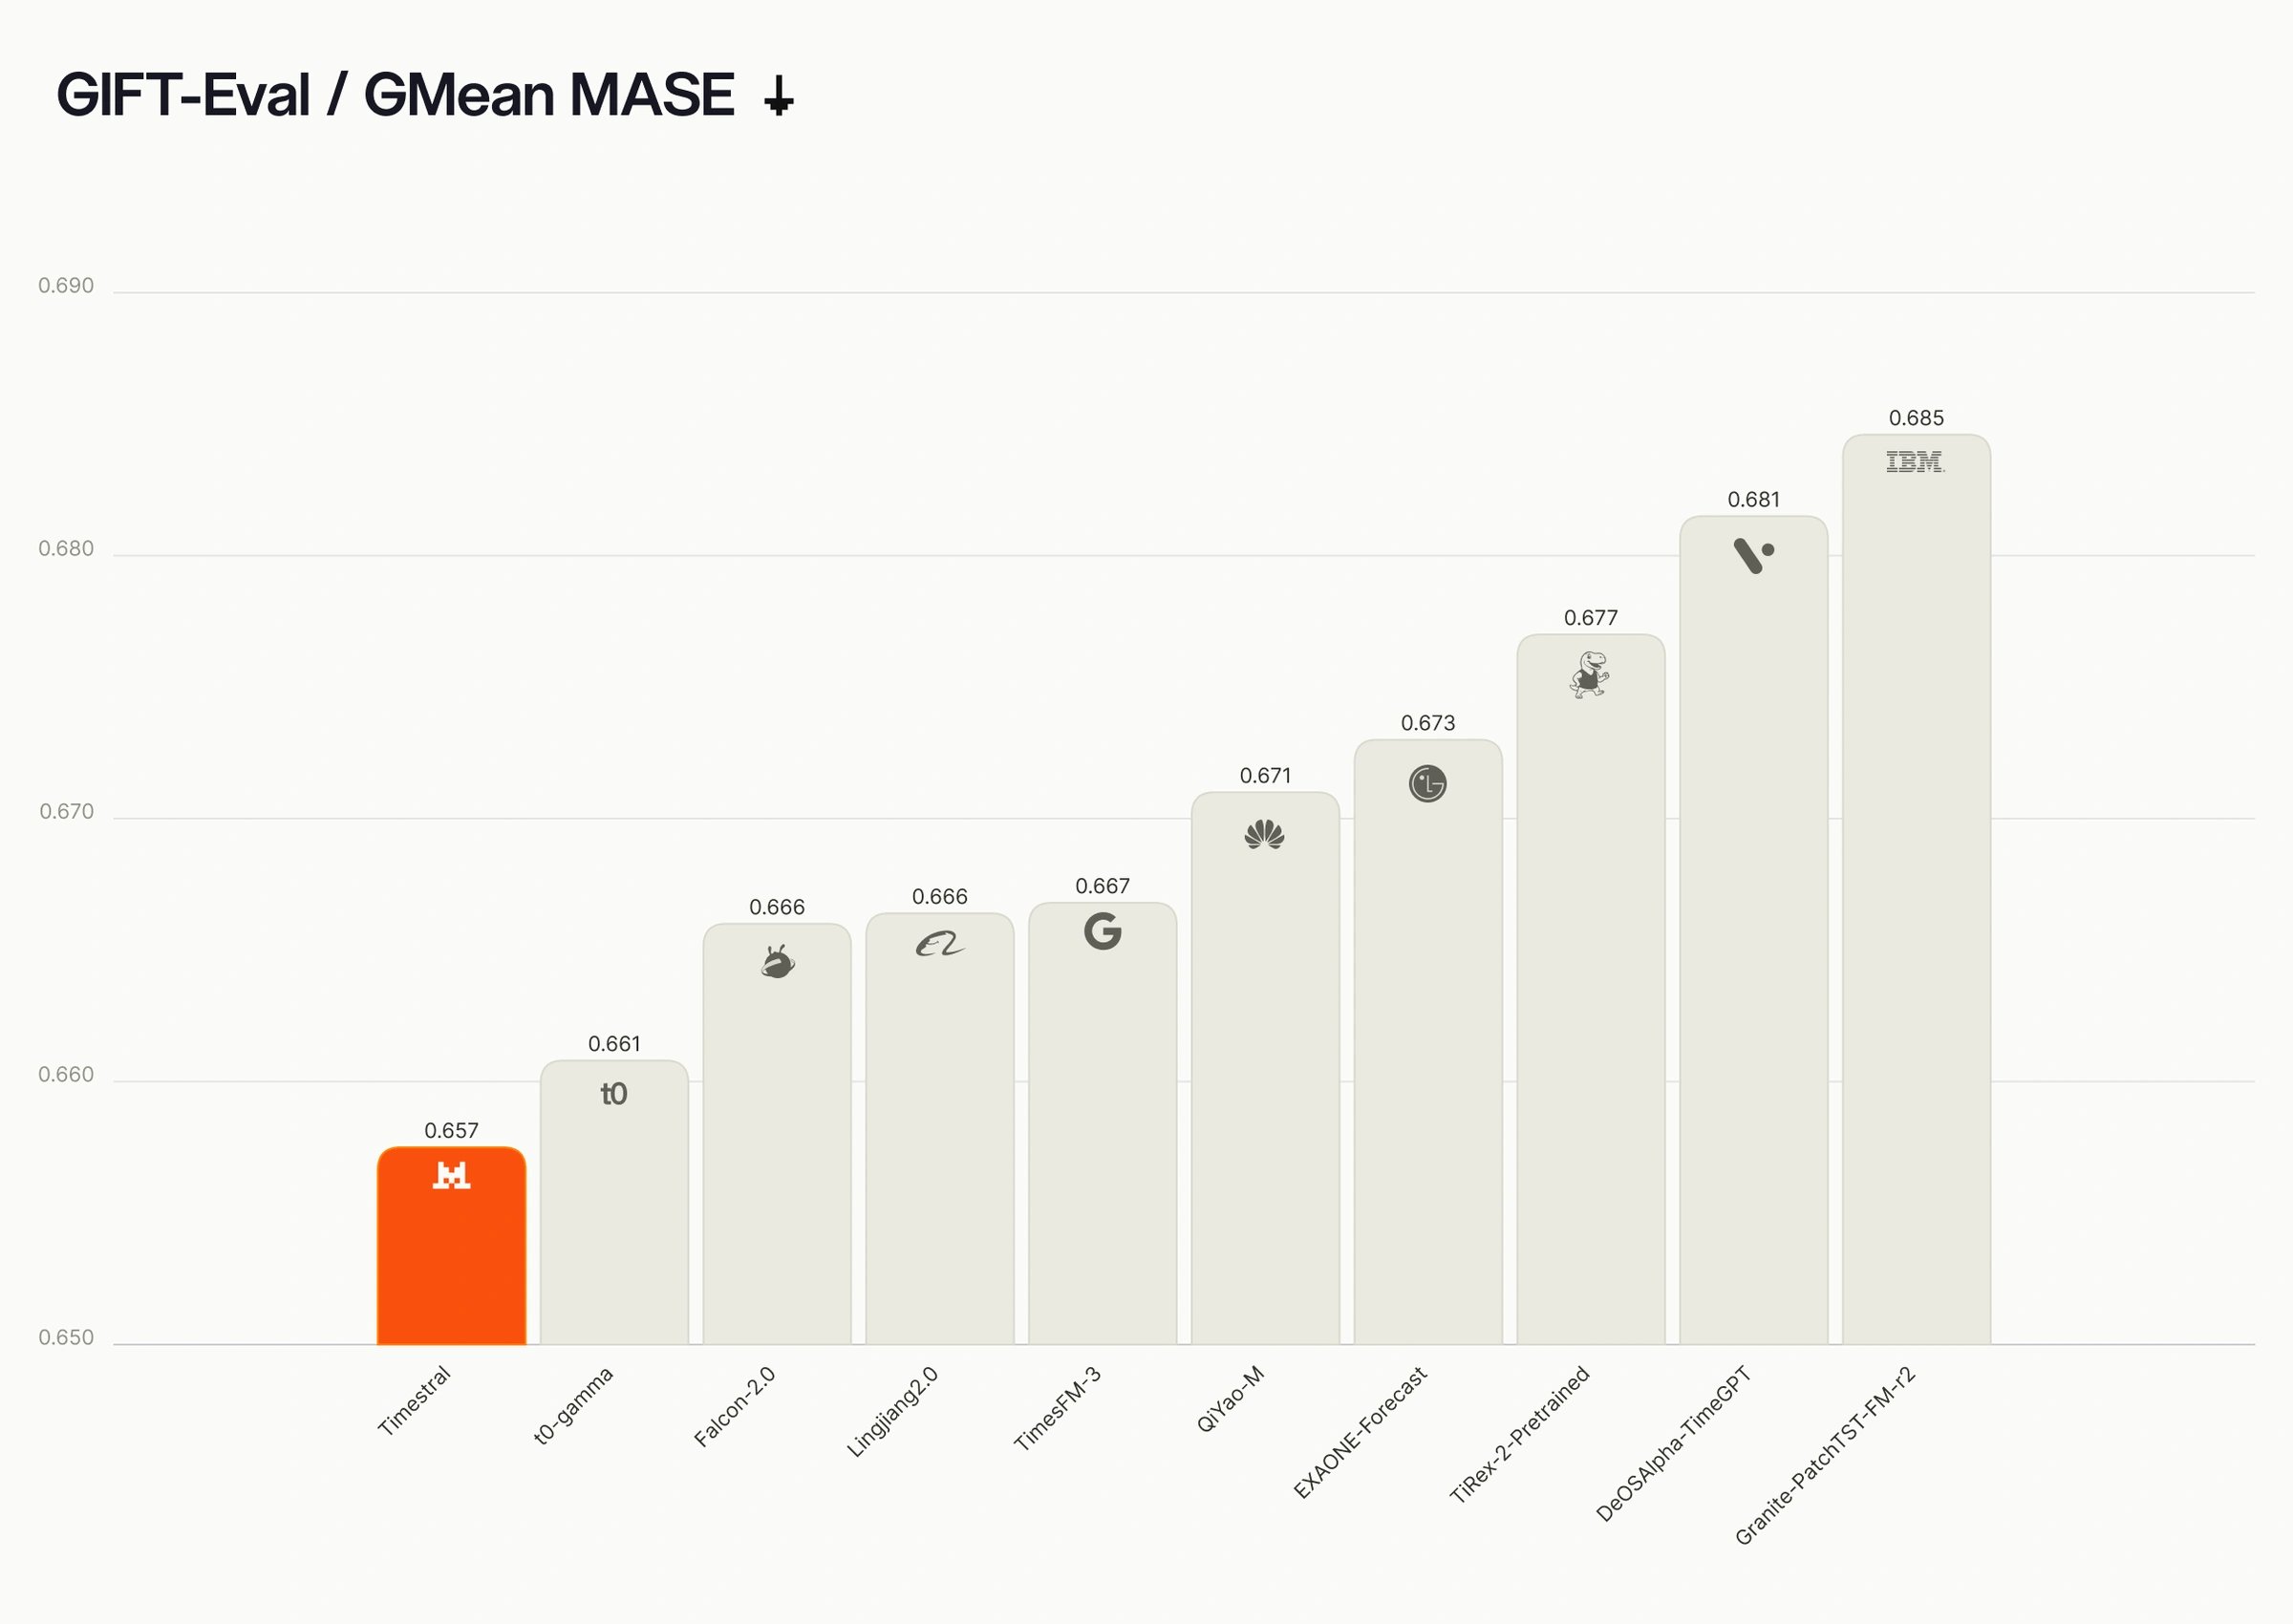
Dropping the GPU entirely, Mistral releases Timestral, four time-series forecasting models from 5M to 209M parameters that top GIFT-Eval, TIME, and fev-bench. The models deliver probabilistic multivariate forecasts without a GPU, handling categorical and known-future covariates zero-shot.
What’s interesting: Forecasting is now a pre-trained, zero-shot problem you can run on a server CPU in milliseconds, with no per-dataset training. That removes a whole modeling step from many pipelines.
Clairic: Extraction Without the LLM
Estimated read time: 11 min
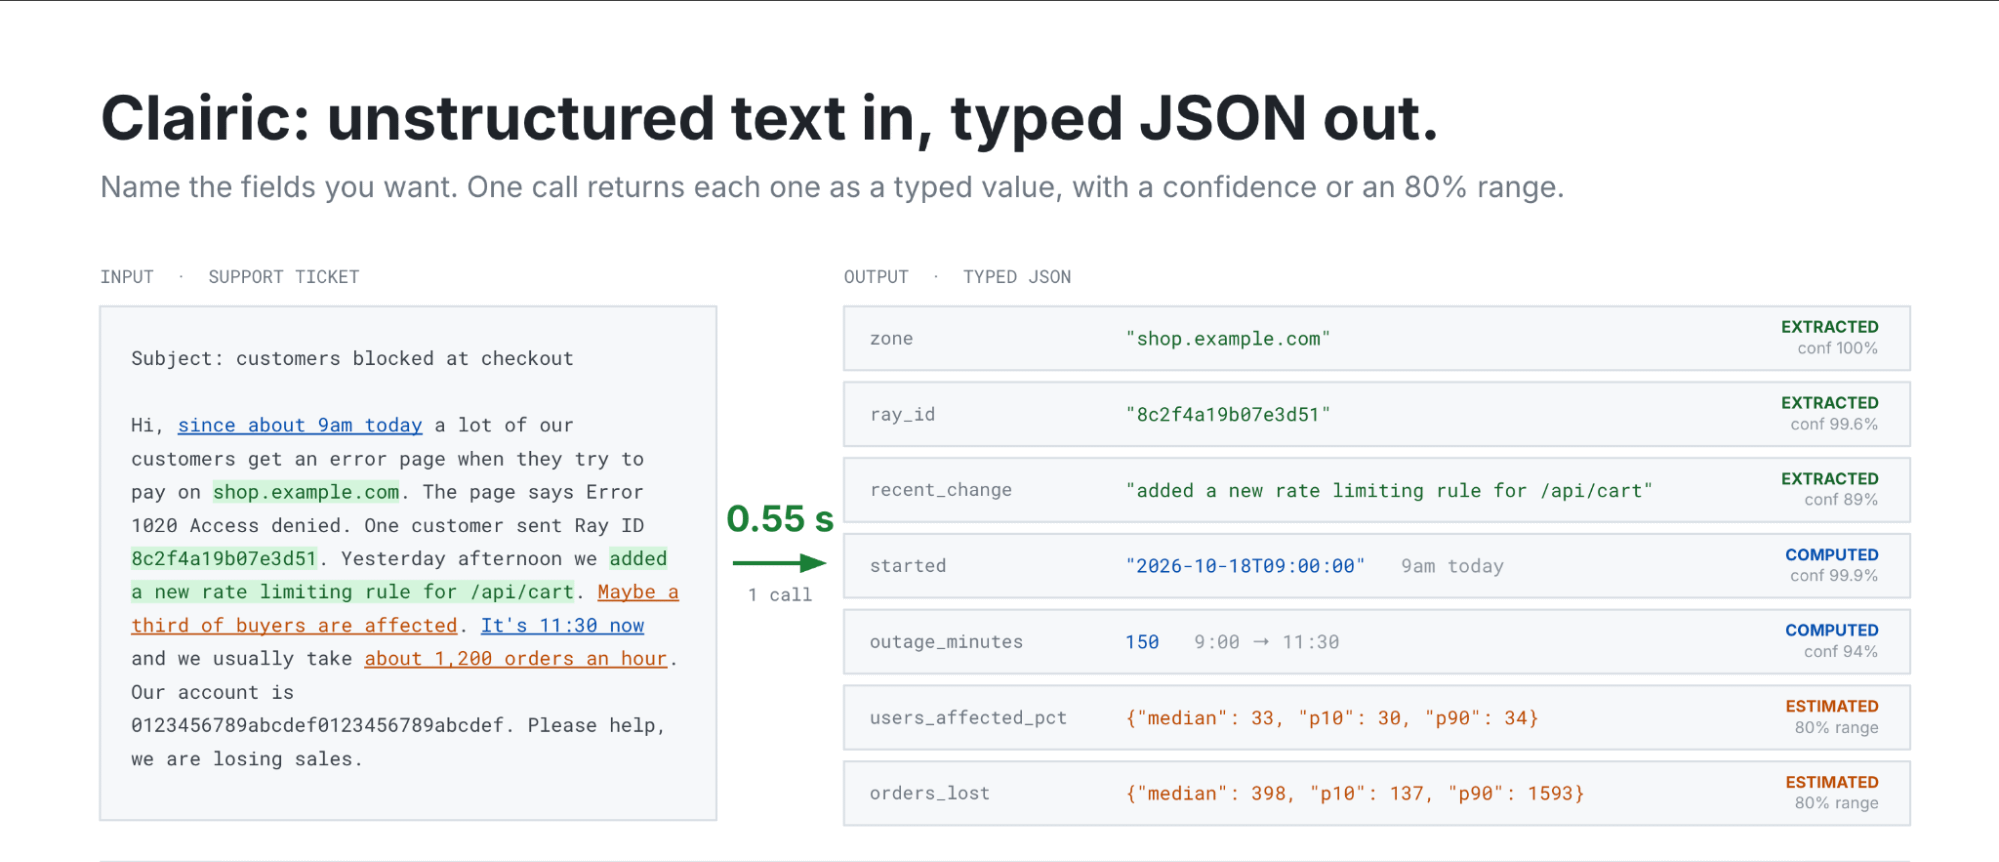
Going one step further, Cloudflare previews Clairic, a “System One” extraction model on Workers AI that returns typed values in a single forward pass: numbers, dates, spans, and forecasts with confidence scores, no output tokens, no hallucinated JSON.
The takeaway: If your pipeline asks an LLM the same structured-output question over and over, a typed single-pass extraction model can do it faster and cheaper, with confidence scores you can route on.
DeepSeek Ships Search and Fetch APIs for Agents
Estimated read time: 6 min
Shifting from models to the services around them, DeepSeek’s new Search and Fetch endpoints give agents and RAG pipelines live web access, returning ranked results with model-ready summaries or clean Markdown pages. Both are billed per successful request, not per token, at $0.75 per thousand.
Worth noting: If your agent needs live web context, these two endpoints replace a scraping stack with flat-rate pricing. You can budget web access per call instead of guessing at token counts.
durable-harness: Coding Agents That Survive a Crash
Estimated read time: 9 min
Closing the section on not paying twice, Vercel introduces durable-harness, open-source adapters that let Pi, OpenCode, Claude Code, and Codex resume an interrupted turn from a durable log instead of repeating finished model and tool calls, running on Vercel, Postgres, or locally.
How to use it: If you run coding agents in the cloud, log each step and mark every tool as safe or unsafe to replay. A crashed turn then resumes instead of redoing paid work.
NEWS & EDITORIALS
The news opens with a piece on the PHP vulnerabilities AI agents found first: the story itself, then the disclosure framework proposed in response. Anthropic’s proactive agent follows, and a short history of hallucination closes the edition.
Frontier AI Found Critical PHP Flaws First. Now What?
Estimated read time: 9 min
Taking the same story from the coalition’s side, OpenAI and partners used frontier models to find the PHP vulnerabilities before attackers did, then proposed a five-stage coordinated disclosure framework for the AI era spanning maintainers, hosting providers, security vendors, and government cyber agencies.
Looking ahead: Disclosure processes built for human-paced discovery are being redesigned for AI-paced discovery. Expect dependency patching to become a routine, scheduled part of your release cycle rather than an occasional scramble.
Claude Duet: Anthropic’s Proactive Agent Comes to You
Estimated read time: 3 min
From agents finding work to agents bringing it to you, Claude Duet flips the chat model: instead of waiting for you to open a thread, it comes to you with morning briefs, drafted replies, and finished work, pausing for approval before sensitive actions.
Key point: Agents are moving from request-response to always-on teammates. That makes approval gates, audit trails, and usage budgets design problems worth planning for now, in your own products too.
The Hallucination Was the Feature
Estimated read time: 6 min
Closing on where that reliability comes from, early neural network pioneers injected randomness deliberately, valuing machines that gave strange answers. A historian traces today’s hallucinations to that choice, arguing creativity and predictability trade off as labs sand the strangeness out of production models.
The reframe: Tuning a model toward reliability costs something on the other end. Decide which of the two your application actually needs before you pick a model or a temperature.